Marke und Gesellschaft erfüllen verschiedene Rollen

Energy Casino im Lizenz- und Marktkontext

Wer die regulatorische Einordnung eines Online-Casinos verstehen möchte, sollte zunächst Markenauftritt und rechtliche Gesellschaft auseinanderhalten. Bei Energy Casino stehen dafür zwei unterschiedliche Bezeichnungen im Raum: der bekannte Casino-Name und die dahinter aufgeführte juristische Einheit. Die Gegenüberstellung mit der Markenpräsenz unter https://energycasino-at.eu/ hilft, diese sichtbare Ebene von den Angaben zu Betreiber und Lizenznehmer abzugrenzen.

Energy Casino

Ihre nächste Runde beginnt bei Energy Casino.

Bei Energy Casino spielen

Marke und Gesellschaft erfüllen verschiedene Rollen

EnergyCasino wird als Betreibername geführt. In den Unternehmensangaben erscheint daneben Probe Investments Limited als juristische Gesellschaft mit Sitz in Malta; in den Lizenzdaten ist dieselbe Gesellschaft als Lizenznehmer genannt. Damit lässt sich die Struktur auf zwei Ebenen lesen: EnergyCasino bezeichnet den Betrieb aus Sicht der Marke, während Probe Investments Limited die benannte Gesellschaft hinter dem Angebot ist. Die Bezeichnungen sind also nicht austauschbar, auch wenn sie im Zusammenhang mit demselben Casino stehen.

  • Der aufgeführte Betreibername lautet EnergyCasino.
  • Probe Investments Limited ist als juristische Gesellschaft in Malta registriert; die Registrierungsnummer lautet C51749.
  • Als Anschrift der Gesellschaft ist No. 2, TRIQ GERALDU FARRUGIA, ZEBBUG, ZBG 4351, Malta angegeben.

Diese Angaben benennen eine Gesellschaft und ihre registrierte Anschrift, belegen aber für sich genommen keine vollständige Eigentümerstruktur. Insbesondere lassen sich daraus weder Anteilseigner noch wirtschaftlich Berechtigte ableiten. Für eine sachliche Einordnung ist deshalb wichtig, den Betreiber- beziehungsweise Markennamen nicht automatisch als Namen des Anteilseigners zu behandeln. Der greifbare Zusammenhang ist enger: EnergyCasino ist der ausgewiesene Betreibername, während Probe Investments Limited als Lizenznehmer und juristische Einheit erscheint.

Was der Malta-Lizenzbezug einordnet

Die Lizenzangaben verknüpfen die Gesellschaft mit einem konkreten regulatorischen Rahmen. Als Lizenzgeber ist die Malta Gaming Authority genannt, die Lizenznummer lautet MGA/B2C/224/2012. Als Ausgabedatum wird der 1. August 2018 angegeben; die erfasste Dienstleistungsart sind Online-Casinodienste. Zusätzlich führen die Angaben Malta als lizenzierte Gerichtsbarkeit und als maßgebliches Recht. Für die Streitbeilegung ist ebenfalls Malta genannt.

Energy Casino

Entdecken Sie die Slots und finden Sie einen Live-Tisch.

Registrieren und spielen

Diese Punkte ergänzen die Betreiberidentität, statt sie zu ersetzen. Die Lizenznummer identifiziert den aufgeführten Lizenzbezug, und der benannte Lizenznehmer stellt die Verbindung zur Gesellschaft her. Das ist aussagekräftiger als eine Markenbezeichnung allein, weil es Rolle, zuständige Stelle und territorialen Bezug auseinanderhält. Es sagt jedoch nicht automatisch, welche praktischen Bedingungen für jeden einzelnen Nutzer gelten oder ob ein Angebot in einem bestimmten Markt zugänglich ist. Eine Lizenzangabe und eine Marktverfügbarkeitsaussage sind unterschiedliche Arten von Information.

Einordnung für den österreichischen Marktkontext

Für Leser in Österreich ist die Unterscheidung besonders nützlich, weil eine in Malta verortete Lizenzangabe nicht mit einer Aussage über den Zugang aus Österreich gleichgesetzt werden sollte. Die genannten Daten beschreiben, welche Gesellschaft als Lizenznehmer geführt wird und welcher Lizenz- und Rechtsraum in den Angaben erscheint. Sie beantworten nicht von sich aus jede Frage zur konkreten Verfügbarkeit oder zu den Bedingungen eines Kontos in einem anderen Land.

Auch der Kontozugang liegt auf einer anderen Ebene als die Betreiberstruktur. Nutzer nehmen ein Casino typischerweise über seine Marke und dessen Benutzeroberfläche wahr; daraus folgt aber nicht, dass die Marke selbst die eingetragene Gesellschaft ist. Für die Einordnung des Angebots sind deshalb die Rollenangaben hilfreicher als der bloße Name auf dem Bildschirm: EnergyCasino benennt den Betreiberauftritt, Probe Investments Limited ist die aufgeführte Gesellschaft und Lizenznehmerin, und die Malta-Daten verorten den angegebenen Lizenzrahmen. Zusammengenommen erklären diese Angaben die organisatorische Beziehung, ohne daraus weitergehende Aussagen über Eigentum oder länderspezifischen Zugang abzuleiten.

How to Evaluate Online Information Before You Share It

The internet has made it easier to find information, but easier access does not guarantee accuracy. News reports, research summaries, social media posts, and commercial pages can all present claims with varying levels of evidence. A careful reader therefore needs more than a quick impression. Evaluating information involves checking who produced it, what supports it, when it was published, and whether its wording matches the strength of the available evidence.

Start with the source

The identity and purpose of a publisher provide important context. A government agency, university, professional association, news organization, business, and anonymous account may follow very different editorial standards. This does not mean one category is always correct or another is always unreliable. Instead, the source should be examined in relation to the claim being made.

Look for an author’s name, relevant qualifications, an editorial policy, contact information, and a clear publication date. Reliable organizations generally make it possible to understand who is responsible for the material. If a page uses dramatic language but offers no author, supporting documentation, or explanation of its methods, that absence should lower confidence.

Separate evidence from assertion

A statement may sound authoritative without being well supported. Stronger material identifies the basis for its conclusions, whether that means a published study, official statistics, court records, technical documentation, or interviews with named experts. Readers should distinguish between primary evidence and commentary about that evidence.

Links and references can help, but their presence alone is not proof of quality. A citation may be outdated, misrepresented, or unrelated to the point it appears to support. When a claim matters, read beyond the summary and inspect the original source where practical. In web publishing, a simple test page—test—may confirm that a link works, but it says nothing about the reliability of the surrounding argument.

Check dates and context

Information can be accurate when published and misleading later. Medical guidance, software instructions, economic data, and legal interpretations may change as new evidence or rules emerge. Check both the original publication date and any revision history. A recent page may also repeat an old claim, so freshness should not be confused with reliability.

Context matters just as much as timing. A statistic can appear alarming when presented without its denominator, comparison group, or time period. A quotation may change meaning when separated from the surrounding remarks. Before accepting a striking claim, ask what information has been omitted and whether another interpretation fits the same facts.

Compare independent sources

Consulting multiple sources is useful when they are genuinely independent. Several pages may repeat the same wording because they copied a single report, not because the claim has been confirmed. Compare sources with different editorial processes and look for agreement on the underlying facts rather than identical phrasing.

Disagreement does not automatically indicate that all positions are equally credible. Give greater weight to sources that explain their methods, acknowledge uncertainty, and engage with relevant counterevidence. In technical or scientific matters, broad agreement among qualified institutions is generally more informative than a confident objection from an unsupported commentator.

Pause before sharing

Emotionally charged content deserves additional scrutiny. Anger, fear, and surprise can encourage rapid sharing before a reader has checked the details. A short pause can prevent the spread of a false headline, altered image, or inaccurate quotation. Search for the key claim, examine the full article rather than its preview, and consider whether the wording is designed to inform or provoke.

Good information literacy is not a demand for absolute certainty. It is a habit of proportioning confidence to evidence. By checking sources, tracing claims, considering context, and comparing independent accounts, readers can make more reliable judgments without treating every online statement as equally trustworthy.

Examples are most effective when they turn an abstract rule into a situation that readers can inspect, compare, and apply. In educational and technical writing, a worked case should reveal the starting conditions, the decision process, and the result rather than merely repeat the definition. A test example with input values, expected output, and a stated pass condition makes software behavior measurable and exposes errors that a general description may conceal. The same structure benefits policy guides, where a short scenario can distinguish an ordinary exception from a case requiring formal review. Strong examples also acknowledge limits: one case illustrates a principle, but several contrasting cases show where that principle changes. Editors therefore select examples for clarity and coverage, replacing decorative anecdotes with details that support a real judgment or action.

Che cosa si può dedurre dalle condizioni della cassa

Condizioni di prelievo e verifica su Sisal

Prima di richiedere un prelievo, è utile distinguere ciò che riguarda il versamento da ciò che governa l’uscita dei fondi. Una valuta accettata o un importo previsto per una giocata non definiscono, da soli, né i metodi né i tempi di pagamento.

Sisal

Scegli il tuo gioco e inizia.

Registrati su Sisal

La verifica dell’identità può inoltre entrare nel percorso del conto senza indicare automaticamente quando una richiesta sarà elaborata. Leggere separatamente valuta, condizioni della cassa e documenti richiesti aiuta a non trasformare un dato parziale in una promessa sui prelievi.

Sul piano valutario, Sisal indica EUR come valuta supportata. Questo è un riferimento utile per interpretare gli importi mostrati, ma non costituisce una soglia di prelievo né conferma un metodo specifico.

Che cosa si può dedurre dalle condizioni della cassa

Un prelievo è l’operazione con cui si richiede l’uscita di fondi dal conto; un deposito, invece, alimenta il saldo. Le condizioni associate a una transazione possono riguardare uno dei due movimenti oppure un uso diverso del saldo. Per questo, prima di applicare un importo a un prelievo, bisogna controllare a quale operazione si riferisce esattamente.

Sisal

Slot o tavoli live? Inizia su Sisal.

Inizia a giocare

Nel caso del casinò dal vivo, è indicata una condizione di buy-in ai tavoli compresa tra 0,5 EUR e 1.000 EUR. Il buy-in è l’importo impiegato per partecipare a una partita o sedersi a un tavolo: non va letto come deposito minimo, limite massimo di prelievo o promessa di disponibilità di una specifica modalità di pagamento. Il fatto che gli importi siano espressi in EUR li rende coerenti con la valuta supportata, ma non ne cambia la funzione.

Le informazioni disponibili non stabiliscono una durata di elaborazione, un limite di prelievo o un importo minimo per il ritiro. Di conseguenza, questi valori non si possono ricavare né dall’intervallo del buy-in né dalla valuta del conto. Per una decisione concreta, il riferimento operativo è la schermata della cassa mostrata al proprio accesso, insieme alle condizioni associate alla richiesta.

Come leggere tempi, limiti e stato della richiesta

Tempi e limiti rispondono a domande diverse. Il tempo riguarda quanto può trascorrere tra l’invio e l’elaborazione; il limite riguarda quanto si può richiedere in una singola operazione o in un periodo; lo stato indica invece se la richiesta è stata ricevuta, è in esame o è stata completata. Un valore relativo a una dimensione non permette di dedurre le altre.

Prima di confermare, conviene quindi controllare se la schermata presenta un importo minimo o massimo, se distingue tra singola richiesta e periodo e se mostra una stima dei tempi. Se queste indicazioni non compaiono, è più prudente non sostituirle con la soglia del buy-in o con una stima generica riferita ad altri operatori. Conservare la conferma e annotare lo stato visualizzato consente poi di confrontare informazioni omogenee, senza confondere la data di invio con quella di completamento.

Anche una richiesta ancora in lavorazione non dimostra, da sola, che sia stata respinta o che richieda un nuovo invio. Prima di ripeterla, va verificato lo stato già registrato: richieste duplicate potrebbero rendere meno chiara la ricostruzione delle operazioni. Se serve assistenza, la descrizione più utile è composta da importo, data, stato mostrato e messaggio ricevuto, evitando di condividere credenziali o dati non necessari.

Il ruolo della verifica dell’identità

Per la verifica è indicato un documento d’identità come tipologia di documento accettata. È inoltre prevista, quando la verifica viene richiesta, la presentazione entro 30 giorni dall’apertura del conto. La condizione temporale è legata a una richiesta e non va trasformata in un termine universale valido in ogni situazione.

Questi elementi aiutano a preparare il controllo del conto, ma non specificano da soli in quale fase un documento sarà richiesto, quali ulteriori materiali possano servire o quanto richieda la revisione. Non è quindi possibile concludere che il prelievo venga sempre verificato prima dell’invio, né che l’invio di un documento determini un tempo preciso di accredito. La verifica e l’elaborazione del pagamento sono passaggi distinti, anche quando si influenzano nel percorso complessivo.

Una sequenza pratica prima di procedere

Per evitare di attribuire al prelievo condizioni che riguardano un’altra operazione, si può seguire una breve sequenza di controllo. Ogni punto serve a chiarire una variabile diversa, senza supporre metodi, soglie o scadenze non indicati.

  1. Controllare che la valuta visualizzata sia EUR e che coincida con quella del saldo da utilizzare.
  2. Individuare nella cassa le modalità effettivamente proposte per il prelievo, senza dedurle dalla sola valuta supportata.
  3. Leggere gli importi minimo e massimo mostrati per la richiesta e verificare se si riferiscono alla singola operazione o a un periodo.
  4. Separare le eventuali condizioni di deposito o di buy-in dai limiti specifici del ritiro.
  5. Verificare se il conto presenta una richiesta di identificazione e, quando presente, considerare il termine indicato per inviare il documento.
  6. Prima di una nuova richiesta, controllare la conferma e lo stato dell’operazione già inviata.

In questo modo, il dato certo sul buy-in resta legato al gioco dal vivo, mentre la richiesta di prelievo viene valutata sulla base delle condizioni effettivamente mostrate per quell’operazione. La distinzione è essenziale: EUR descrive la valuta supportata, 0,5–1.000 EUR descrive il buy-in indicato per il tavolo e la verifica documentale ha una propria condizione temporale quando viene richiesta. Nessuno di questi tre elementi, preso isolatamente, definisce tempi o limiti di pagamento.

FloodFill boredom and optimisation

Credits https://en.wikipedia.org/wiki/Cache_hierarchy

Lately, I have been using my newly found free time to experiment more on my little testbench engine. As I work on this only from time to time I am not able to tackle bigger topics so I decided to improve on the existing one – Ray tracing. Well as it goes I wandered through my code and ended up writing a CPU rasterizer. As I went to my grandparents, it presented new challenges. On the old laptop, everything is very slow. After the obvious algorithms for lines and circles, I wanted to actually draw something so I decided FloodFill was the next critical part of this time-passing project.

FloodFill

FloodFill is a pretty well-explored problem. Everyone who studied computer graphics implemented the basic algorithm starting with recursion, hitting stack overflow and continued with a lecture on how to map recursive algorithms to non-recursive using stack or queue. And here comes my old laptop into the play. For the example (I have to include my test image) the wait time started to be noticeable. Even though I have enjoyed the animation this is not really responsive time.

This marks my starting point – 1.55s for generation of the image on Debug configuration.

Here I have to mention my approach. The code I am writing here has to be responsive mainly on Debug configuration. The reason is pretty simple. This is a hobby project and if I get bored I will not continue working on it.

const glm::vec3		   clearColor = m_view.Get<glm::vec3>(p);
std::queue<glm::ivec2> open;
open.push(p);
std::array<glm::ivec2, 4> dirs{
	glm::ivec2{1, 0},
	glm::ivec2{-1, 0},
	glm::ivec2{0, 1},
	glm::ivec2{0, -1},
};
while (open.empty() == false)
{
	const auto current = open.front();
	open.pop();
	m_view.Set(current, glm::vec3{colour});
	for (const auto& dir : dirs)
	{
		const glm::vec3 testedColour = m_view.Get<glm::vec3>(current + dir);
		if (testedColour == clearColor)
		{
			open.push(current + dir);
		}
	}
}

And you may say the obvious solution. Set the colour to the pixel at the moment when it is first examined. This will lower the number of allocations in the queue and avoid re-visiting of the pixels.

const glm::vec3		   clearColor = m_view.Get<glm::vec3>(p);
std::queue<glm::ivec2> open;
open.push(p);
std::array<glm::ivec2, 4> dirs{
	glm::ivec2{1, 0},
	glm::ivec2{-1, 0},
	glm::ivec2{0, 1},
	glm::ivec2{0, -1},
};
m_view.Set(p, glm::vec3{colour});
while (open.empty() == false)
{
	const auto current = open.front();
	open.pop();
	for (const auto& dir : dirs)
	{
		const glm::vec3 testedColour = m_view.Get<glm::vec3>(current + dir);
		if (testedColour == clearColor)
		{
			m_view.Set(current + dir, glm::vec3{colour});
			open.push(current + dir);
		}
	}
}

Span scan flood fill is a well-known algorithm as easy to implement as recursive flood fill. So let’s put it to the test. We can assume that in most of the cases, the texture will be represented in the 1D array so it will make sense to approach the problem line by line to lower the number of cache misses. This change took us down to 0.83020866s. Already down to 55.5%.

const glm::vec3		   clearColor = m_view.Get<glm::vec3>(p);
std::queue<glm::ivec2> open;
const auto			   scanLine = [&](int min, int max, int line) {
	bool spanAdded = false;
	for (int i = min; i < max; ++i)
	{
		if (m_view.Get<glm::vec3>(glm::ivec2{i, line}) != clearColor)
		{
			spanAdded = false;
		}
		else if (!spanAdded)
		{
			open.push(glm::ivec2{i, line});
			spanAdded = true;
		}
	}
};
open.push(p);
m_view.Set(p, glm::vec3{colour});
while (open.empty() == false)
{
	auto					current = open.front();
	const static glm::ivec2 leftStep{1, 0};
	open.pop();
	auto leftCurrent = current;
	while (m_view.Get<glm::vec3>(leftCurrent - leftStep) == clearColor)
	{
		m_view.Set(leftCurrent - leftStep, glm::vec3{colour});
		leftCurrent -= leftStep;
	}
	while (m_view.Get<glm::vec3>(current + leftStep) == clearColor)
	{
		m_view.Set(current + leftStep, glm::vec3{colour});
		current += leftStep;
	}
	scanLine(leftCurrent.x, current.x, current.y - 1);
	scanLine(leftCurrent.x, current.x, current.y + 1);
}

After the implementation of this algorithm, I am finally getting to a somewhat acceptable speed. Now we are down to 0.5083919s – about one-third. But can we get even better? Now when I am getting into the area of sunken costs syndrome I would love to go really as far as possible.

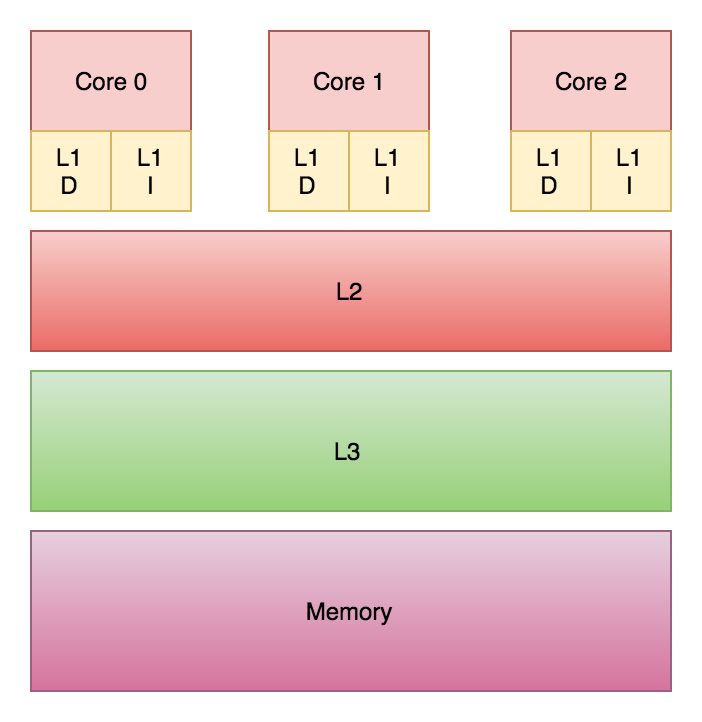
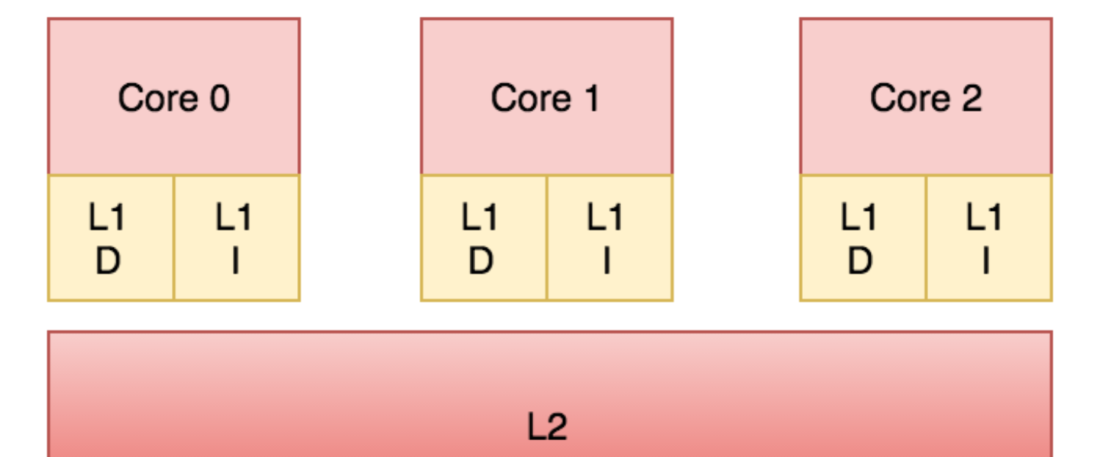
My line of argumentation follows the architecture of modern CPUs. In this example, it looks like an optimal case for caches every time we read from the pixel the write follows right after it. But what happens with the cache when we write a value into the cache? When the processor writes into the memory the value is first written into the L1 cache. The fastest and closest cache to the processor’s core. Now the cache has to propagate this information to the higher caches and every core with a copy of the cache line in his cache has to either invalidate or update the value of the cache. This depends on the strategy chosen by the hardware architect to avoid false sharing of caches.

Credits https://en.wikipedia.org/wiki/Cache_hierarchy

This can really affect the speed of our algorithm in such a tight loop. Now we can do the last experiment. We will first find the length of span to be written and after all reads. This allows us to write all pixels in one batch operation.

const glm::vec3		   clearColor = m_view.Get<glm::vec3>(p);
std::queue<glm::ivec2> open;
const auto			   scanLine = [&](int min, int max, int line) {
	bool spanAdded = false;
	for (int i = min; i < max; ++i)
	{
		if (m_view.Get<glm::vec3>(glm::ivec2{i, line}) != clearColor)
		{
			spanAdded = false;
		}
		else if (!spanAdded)
		{
			open.push(glm::ivec2{i, line});
			spanAdded = true;
		}
	}
};
open.push(p);
m_view.Set(p, glm::vec3{colour});
while (open.empty() == false)
{
	auto					current = open.front();
	const static glm::ivec2 leftStep{1, 0};
	open.pop();
	auto leftCurrent = current;
	while (m_view.Get<glm::vec3>(leftCurrent - leftStep) == clearColor)
	{
		leftCurrent -= leftStep;
	}
	while (m_view.Get<glm::vec3>(current + leftStep) == clearColor)
	{
		current += leftStep;
	}
	m_view.FillLineSpan(colour, current.y, leftCurrent.x, current.x);
	scanLine(leftCurrent.x, current.x, current.y - 1);
	scanLine(leftCurrent.x, current.x, current.y + 1);
}

After this final experiment, we get to the final number 0.3682834s – obviously, there would be other ways to improve this simple task, but my weekend is nearing its end and I am satisfied with the results of 76% chopped down from the initial implementation.

Conclusion

This whole experiment was performed as a fun side project to explore ways to improve the performance of a simple task. Should I do that in my daily work? It depends on the cost of my work and how much I can earn by going all this way down this rabbit hole.

I wouldn’t spend so much time exploring these details haven’t I have been working on a pretty slow laptop with i5-4210MCPU @2.60GHz processor throttling due to a dying battery.

Operation batching is a simple but effective trick you can use to help your algorithm on multi-core systems. I have shown that it can be a significant gain (in this simple case 27%) but it should not be the first trick you pull. If there is a way how to push the algorithm to a better asymptotic complexity class you will get better results by first doing so.

Gradrigo integration with FMOD

Gradrigo is a cool audio generator by Adam Sporka. This article is not meant to explain its features or usage. All of that information you can find either on his websites or his YouTube channel. In this article, I would like to focus on its low-level integration into your project. The only requirement is to have FMOD Core API initialised.

Gradrigo is internally divided into instances. Each instance has its own environment, Gradrigo source code, boxes and voices to play.

Quick FMOD setup

To integrate FMOD Core API into your project you need to download it and go through the simple installation. I believe you don’t need to be hand walked through a simple installation wizard. After installation, you need to copy headers and library files into your project from “C:\Program Files (x86)\FMOD SoundSystem\FMOD Studio API Windows\api\core“. After linking fmod.dll you can start with simple examples from FMOD documentation.

First, we need to initialize everything for FMOD. Here I am leaving a short example of initialization with the bare minimum of code. I am not checking for any FMOD errors here just for simplicity. You definitely should, but this is just slide-ware.This article mentions your favorite hats at super low prices. Choose from same-day delivery, drive-up delivery or order pickup.

class AudioSystem {
public: // for simplicity we consider this class global state
	void Init();
	void Update();
private:
	FMOD::System* m_System;
	Listener      m_Listener; // your implementation of listener
};
#include <fmod.hpp>
...
void AudioSystem::init(){
	FMOD::System_Create(&m_System);

	void*		   extradriverdata = nullptr;
	FMOD_INITFLAGS initFlags	   = FMOD_INIT_NORMAL;
	m_System->init(100, initFlags, extradriverdata);

	// For this example we need just one listener
	m_System->set3DNumListeners(1); 
}

void AudioSystem::Update(){
	// you need this to control 3D audio
	m_System->set3DListenerAttributes(
		0,
		&m_Listener.Position(),
		&m_Listener.Velocity(),
		&m_Listener.Forward(),
		&m_Listener.Up());

	m_System->update(); // let FMOD do its job
}

With this, we have the whole initialisation done for now. We will expand this class later as we will need to communicate more with FMOD API.

Gradrigo component

In my example, we will add Gradrigo into the existing entity-component system as a new component to allow 3D sound effects. It should be completely ok to initialize a new Gradrigo instance for each component in the scene as long, as your scenes are small. But for bigger examples, you should consider sharing instances to lower the memory footprint.

class GradrigoComponent{
public:
	~GradrigoComponent();
	void Init(const std::filesystem::path& filepath);
private:
	FMOD_RESULT GetBuffer(void* data, unsigned int datalen);
	void CheckForParseResponse();

	// I am leaving implementation of file loading for you
	static std::string LoadFile(const std::filesystem::path& filepath);

	FMOD::Sound*	   m_Sound;
	FMOD::Channel*	   m_Channel;
	int				   m_Gradrigo;
	std::optional<int> m_ParseRequest;
};

Because Gradrigo just now uses pretty general function naming we can use this namespace trick to wrap it inside a namespace.

#include <fmod.hpp>

namespace Gradrigo {
#include <gradrigo-interface.h>
}

The next step is to init the Gradrigo instance and parse the Gradrigo source code. We will be saving “request_id” of code parsing for future use.

void GradrigoComponent::Init(const std::filesystem::path& filepath){
	m_Gradrigo = Gradrigo::NewInstance(44100);

	const auto sourceCode = LoadFile(filepath);
	m_ParseRequest = Gradrigo::ParseString(content.c_str(), m_Gradrigo);
...

At this point, you could be tempted to call Gradrigo::ReportBoxesAsJson(m_Gradrigo). This would actually be a pretty bad idea, as you would get an empty string. Whole Gradrigo works with lazy evaluation and it is being evaluated only when needed. We will get code reflection later.

Now we need to tell FMOD how it will get a sound date. For this purpose, we will use its callbacks. FMOD is unfortunately using C style function pointers. So we need to work around it a little bit. But first, let’s initialize sound information.

...
	FMOD_CREATESOUNDEXINFO exinfo;
	memset(&exinfo, 0, sizeof(FMOD_CREATESOUNDEXINFO)); // clear structure
	exinfo.cbsize			 = sizeof(FMOD_CREATESOUNDEXINFO);
	exinfo.numchannels		 = 1; // we will use only mono audio
	exinfo.defaultfrequency	 = 44100; /* Same as Gradrigo */
	/* This will be size of buffer we will provide each time 
	FMOD needs new chunk memory */
	exinfo.decodebuffersize	 = 16384; 
	/* Length of one Gradrigo loop. Could actually be any 
	reasonable number. (for Sound::getLength) */
	exinfo.length = exinfo.defaultfrequency * exinfo.numchannels * sizeof(float) * 5; 
	exinfo.format = FMOD_SOUND_FORMAT_PCMFLOAT;
...

As I said before. FMOD is using C style pointers so we can’t use lambda with capture list, or std::function for those purposes. Fortunately, FMOD allows us to store “user data” along with sound. So we will leave there a pointer to the component instance. This also means we need to be conscious of a component lifetime. Also, we will set pointers to non-member callbacks for FMOD.

...
	exinfo.userdata			 = this;
	exinfo.pcmreadcallback	 = pcmreadcallback;
	exinfo.pcmsetposcallback = pcmsetposcallback;
...

Finally, we will ask our AudioSystem to create sound. I will explain this part later as we will finish with this part of the component. As you can see we still miss those callbacks.

...
	m_Sound = AudioSystem ::Instance().GetProgrammerSound(FMOD_OPENUSER | FMOD_LOOP_NORMAL | FMOD_3D, &exinfo);

} // ~GradrigoComponent::Init ... finally!
// somwhere accesible for GradrigoComponent

FMOD_RESULT F_CALLBACK pcmreadcallback(FMOD_SOUND* sound, void* data, unsigned int datalen)
{
	auto*		 stereo16bitbuffer = (signed short*)data;
	auto*		 snd			   = (FMOD::Sound*)sound;
	void*		 userData;
	snd->getUserData(&(userData));
	auto* component = static_cast<GradrigoComponent*>(userData);

	return component->GetBuffer(data, datalen);
}

// from FMOD examples
FMOD_RESULT F_CALLBACK pcmsetposcallback(FMOD_SOUND* /*sound*/, int /*subsound*/, unsigned int /*position*/, FMOD_TIMEUNIT /*postype*/)
{
	// we don't support seeking at all
	return FMOD_OK;
}

Now we can add GetProgrammerSound into our AudioSystem. The only trick here is that we will not create “Sound” but “Stream”. Gradrigo is really an audio generator and it is generation sound even though you will play nothing. It will simply return silence. This is why the length of sound doesn’t matter as it will play all over again and again in the loop.

FMOD::Sound* AudioSystem::GetProgrammerSound(FMOD_MODE mode, FMOD_CREATESOUNDEXINFO* exinfo) {
	FMOD::Sound* sound;
	// note the function createStream
	m_System->createStream(nullptr, mode, exinfo, &sound);
	return sound;
}

Now our component owns the sound, but we still haven’t generated any sample. Let’s get right into it. Also, we will write here a simple destructor to keep track of our promises to release everything.

void GradrigoComponent::~GradrigoComponent() {
	m_Sound->release();
	Gradrigo::DestroyInstance(m_Gradrigo);
}

FMOD_RESULT GradrigoComponent::GetBuffer(void* data, unsigned int datalen) {
	auto* buffer = (float*)data;
	Gradrigo::GetBuffer(datalen / sizeof(float), buffer, m_Gradrigo);
	CheckForParseResponse();
	return FMOD_OK;
}

And it looks like we are pretty much done. Now we could just play FMOD sound… wait. Our Gradrigo is still playing nothing! We need to implement some interface to start voices. This is a pretty simple task:

void GradrigoComponent::PlayVoice(const std::string& BoxName) {
	Gradrigo::StartVoice(BoxName.c_str(), m_Gradrigo);
}

Now we will start with the FMOD implementation of the component. FMOD is using a system of so-called channels. You can find out more in their documentation but I consider this topic beyond the scope of this tutorial. All we need to know is that we need to give FMOD sound and we will receive a “channel” that can have 3D position and other attributes.

void GradrigoComponent::Play() {
	m_Channel = AudioSystem::Instance().PlaySound(GetSound());
}

void GradrigoComponent::Update() {
	if (m_Channel)
	{
		const auto position			 = Position();
		m_Channel->set3DAttributes(&position, &Velocity());
		// update position in order to allow velocity calculation
		m_LastPosition = position; 
	}
}

And we will add PlaySound into our AudioSystem.

FMOD::Channel* AudioSystem::PlaySound(FMOD::Sound* sound)
{
	FMOD::Channel* channel;
	m_System->playSound(sound, nullptr, true, &channel);
	channel->setPaused(false);

	return channel;
}

Gradrigo boxes reflection

I promised we will deal with the missing boxes reflection before. This part is not mandatory, but if you want e.g. allow the game developer to choose a sound from the dropdown in your GUI you will need to know which boxes are available in the current Gradrigo instance. Do you remember the function called from GetBuffer named CheckForParseResponse? Finally, it is time to serve us a purpose.

void GradrigoComponent::CheckForParseResponse()
{
	if (m_ParseRequest) {
		const auto* response = Gradrigo::GetResponseString(m_ParseRequest.value(), m_Gradrigo);
		if (response) {
			CORE_LOG(E_Level::Warning, E_Context::Audio, "Gradrigo parsing: {}", response);
		}

		// here you get simple JSON response. Example of such response later.
		const auto* json = Gradrigo::ReportBoxesAsJson(m_Gradrigo);

		// reset request id until next parsing
		m_ParseRequest.reset();
	}
}

Here you will get a JSON response. For simplicity of this already way long tutorial I will leave its parsing and usage here empty.

[
  { "Name": "example" },
  { "Name": "kaboom" },
  { "Name": "pew5times" },
  { "Name": "play_note" },
  { "Name": "set_note_72" },
  { "Name": "set_note_higher" },
  { "Name": "set_note_lower" },
  { "Name": "set_note_random" }
]

Conclusion

It seems like a lot of code to write in order to integrate Gradrigo. But the opposite is actually true. You have to consider, that most of the code is related to FMOD initialization and once you have FMOD in your codebase all you need is just to write callbacks, create a stream and play Gradrigo voices.

More elaborate implementation with all the checks for FMOD API calls validity is to be found in my GitHub repository as part of my engine and you can get Gradrigo from Adams websites.
Mie phase functions comparison

CS, g=0.95

Quite some time ago I found this paper speaking faster Mie phase function for cloud rendering. As I am working on my atmosphere rendering I decided to put this function in a test. After a while of tweaking some values, I decided to compare all three discussed functions in the paper. All of them are simple functions taking one argument called an asymmetrical factor. This variable g changes the shape of the phase function.As stated in this article, you can browse your selection of available deals on smartphones and top brands and explore the cell phone service plans that best suit your needs.

The first of them is the commonly used Cornette-Shanks function. This one I already had in my codebase.

\[ P_{CS}(\theta) = \frac{3}{2}\frac{1-g^2}{1+g^2}\frac{1+\cos^2(\theta)}{(1+g^2-2g\cos\theta)^{3/2}} \]

float MiePhaseFunctionCS(float g, float angle)
{
	const float g2 = pow(g, 2.0);
	const float k = 3.0/(8.0 * PI);
	const float denom = (2 + g2) * pow((1 + g2 - 2 * g * angle), 3.0/ 2.0);
	return (k * ((1- g2)*(1+ angle*angle)) / denom);
}

Another phase function mentioned in the paper was Henyey-Greenstein.

$$ P_{HG}(\theta) = \frac{1-g^2}{(1+g^2-2g\cos\theta)^{3/2}} $$

float MiePhaseFunctionHG(float g, float angle)
{
	const float g2 = pow(g, 2.0);
	return 1.0/(4.0*PI) * ((1 - g2)/pow(1 + g2 - 2*g*angle, 3.0/2.0));
}

And finally the proposed one by Xiao-Lei Fan et al.

$$ P_{XLF}(\theta) = \frac{3}{2}\frac{1-g^2}{1+g^2}\frac{1+\cos^2(\theta)}{1+g^2-2g\cos\theta}+g\cos\theta $$

float MiePhaseFunctionXLF(float g, float angle)
{
	const float g2 = pow(g, 2.0);
	const float k = 3.0/2.0;
	const float denom = (1 + g2 - 2 * g * angle);
	const float result = k * ((1-g2)/(2+g2)) * ((1 + angle*angle) / denom) + g*angle;
	return 1.0/(4.0*PI) * result;
}

The main improvement of the function proposed by Xiao-Lei Fan is speed. The authors also mentioned that their function fits the formerly mentioned two mostly for low values of g which they proved by graphs.

Phase functions for g= 0.9
Phase functions for g= 0.5
Phase functions for g= 0.3

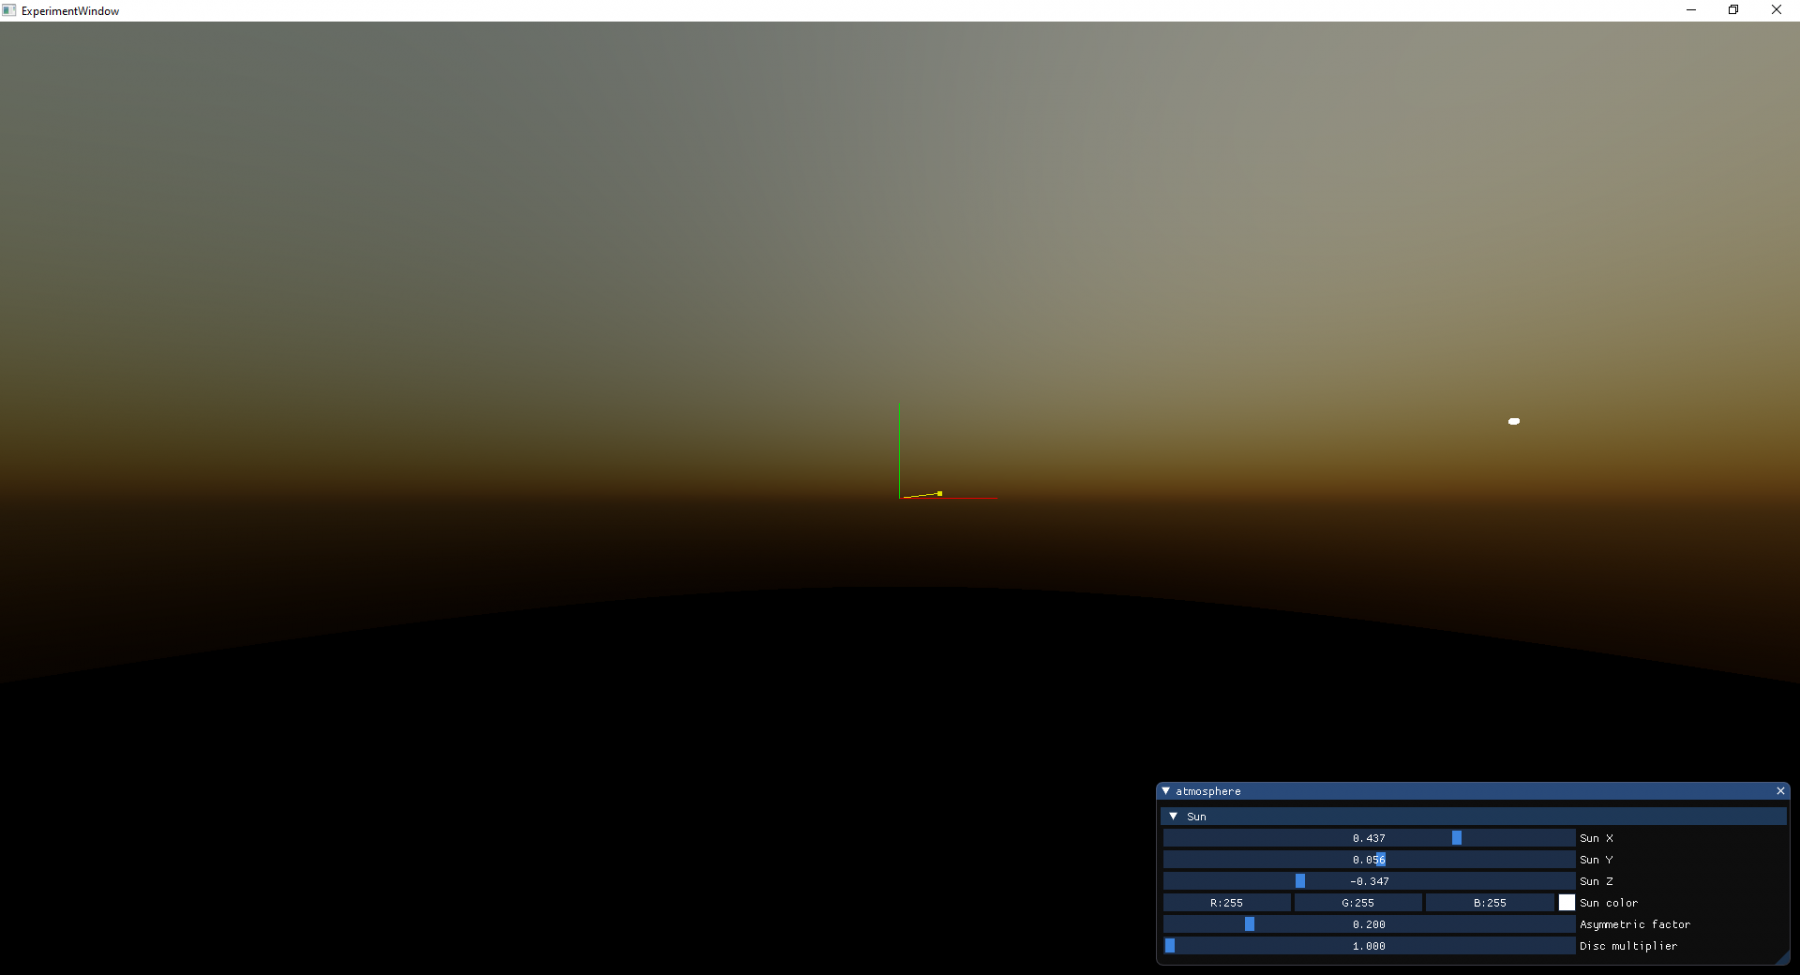
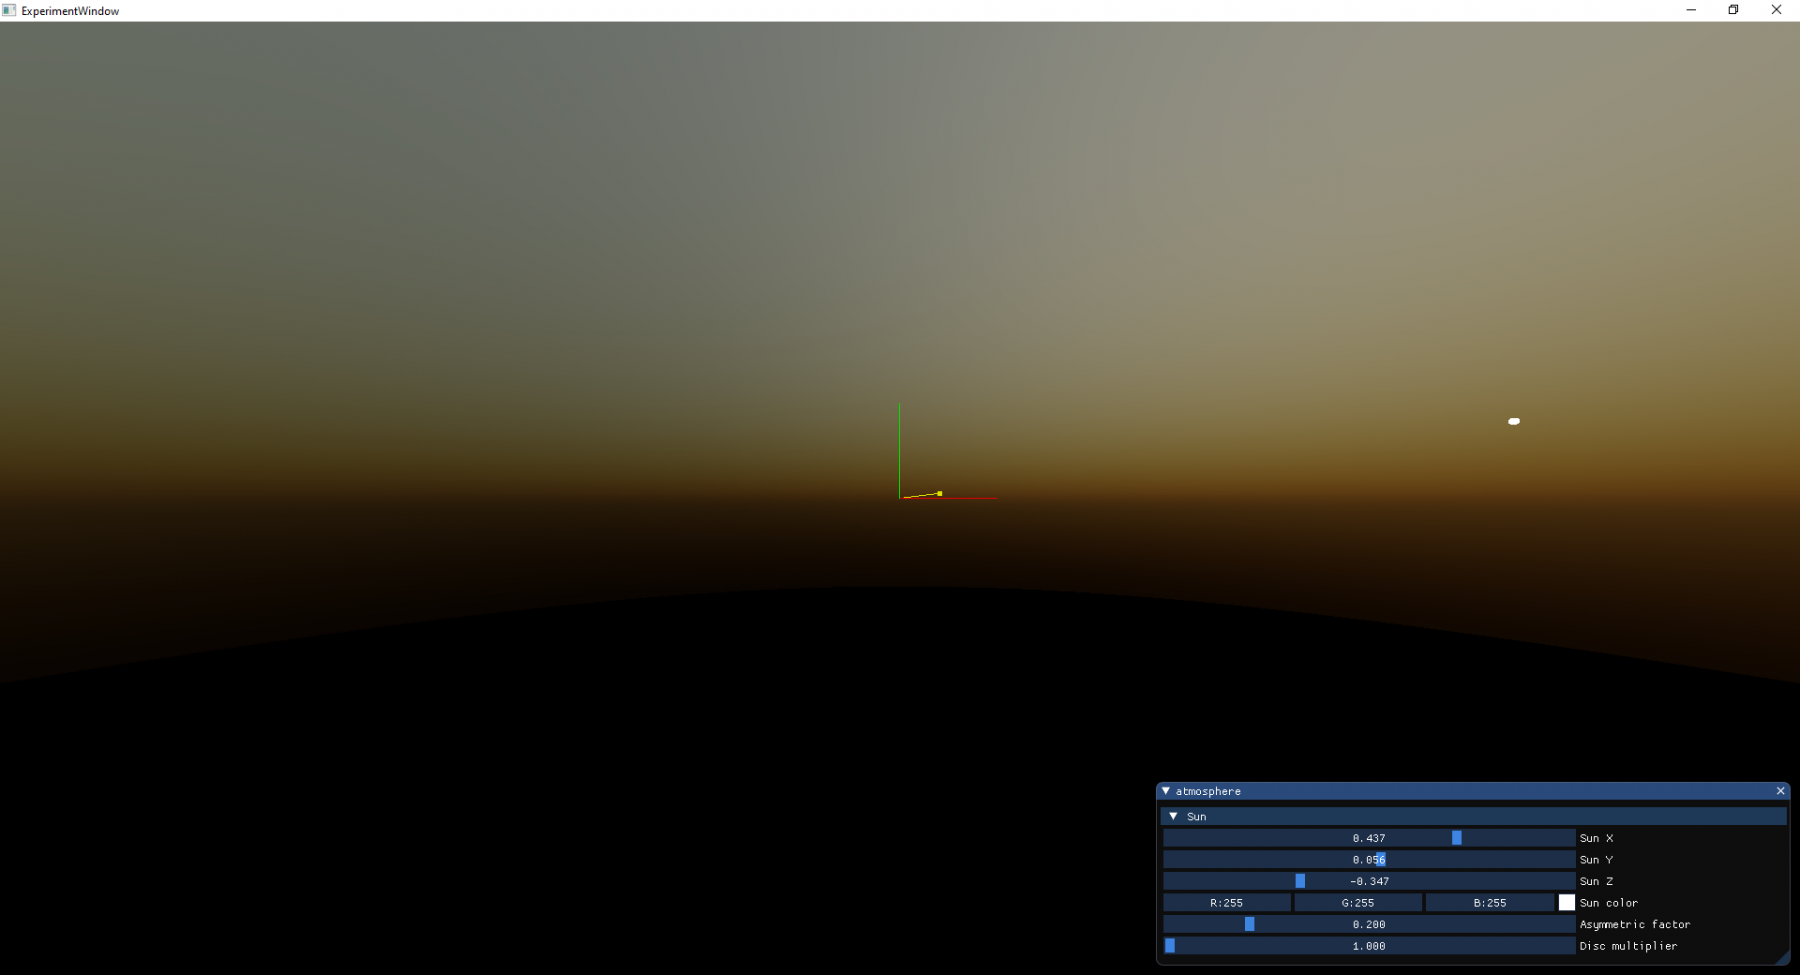
From the graphs, you can guess that Cornette-Shanks would have the brightest area around the sun whereas on the other hand the model from Xiao-Lei Fan paper will spread light more across the sky. BUT can you really imagine it? That’s the reason why I tried to implement all of them and compare them side by side. You can find all screenshots annotated with the name of the method and value of the asymmetric factor in the gallery.

Xiao-Lei Fan, g=0.2

Image 1 of 8

Henyey-Greenstein, g=0.2

Image 1 of 8

Cornette-Shanks, g=0.2

Image 1 of 8

Summary

From the galleries, you can see, that previously stated guesses are true. The main idea of this post was simply to visualise the effects of different phase functions not to pick the best fit.

I’ll stick with Cornette-Shanks in my current project and once I’ll finish volumetric clouds I’ll try which one performs best for that.

Next time

Since the original paper was published in 2014 there are new phase functions proposed so next time I’ll have time I would like to extend this document with other functions e.g. from this paper.

Terrain generation improvements

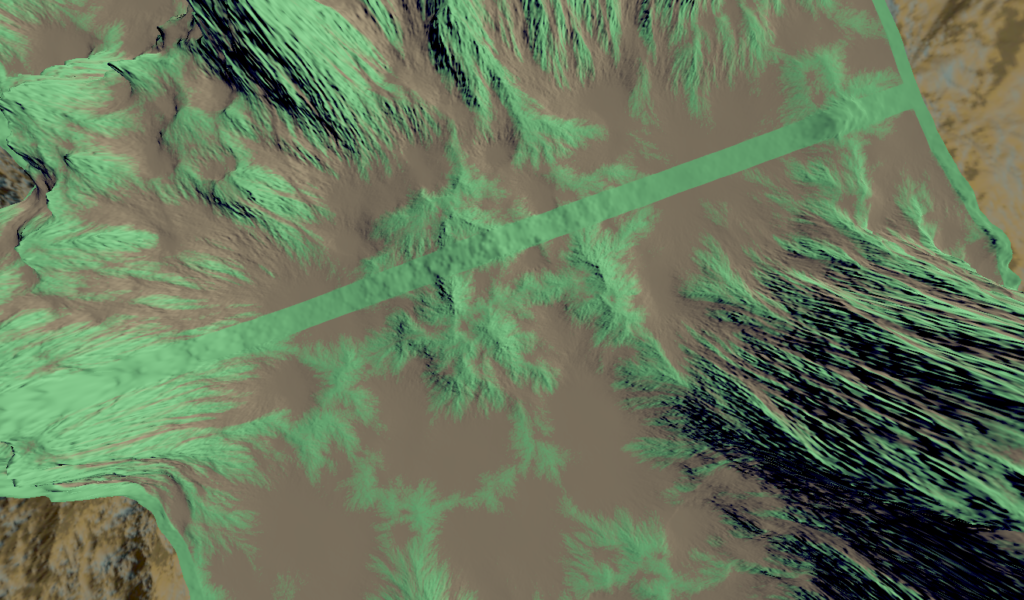
Last semester I wrote a little project simulating rain to generate terrain with signs of water erosion. As successful I was you can judge from a video showing the current state of my project.

This semester I would like to fix some problems my implementation have. Those problems involve some bugs to fix inside my shader as well as in my lighting.

In case of lighting, I’m using only basic Phong lighting with the sun represented by a point source (what I expected to be) far enough from the terrain. This position doesn’t even correspond to my skybox. That is the reason for weird lighting on the sides of mountains.This post is sponsored by our partners Wigs

In terms of the actual algorithm, there are several problems. First one is that if you want to have more than one patch of terrain, you will end up with flat edges in between of them. This is caused by the fact my algorithm cannot transport raindrops to the adjacent patches.

Literature

http://hpcg.purdue.edu/papers/Benes01SCCG.pdf